A dashboard built around useful work
LunarCrush · In progress
Turning two product conversations into a presentation, a revised onboarding audit, and an ordered plan for dashboard and recipes.
Today I revised a LunarCrush presentation after two product conversations. The work changed the direction of the deck, the onboarding audit behind it, and the order of the next design tasks. The central question became more specific: what should a team be able to accomplish when it enters the product?
The opening slide in Paper, captured on September 21. It records a direction and a proposed delivery sequence; it is not a screenshot of a released dashboard.
A change in the starting point
The updated direction puts the dashboard at the center of the experience, with recipes, tools and connections helping users put social intelligence to work. Enterprise teams, marketers and agencies are the priority audience in the meeting notes. That changes which examples belong at the entrance and what onboarding needs to prepare.
My earlier plan included a possible Bitcoin recipe pilot. I revisited that candidate against the new audience. A brief comparing a brand with its competitors is now a design candidate worth evaluating. It still needs confirmation against data coverage and supported tools; it is not an implemented workflow.
Making the presentation carry the decision
I updated the eleven-slide presentation in Paper and the written plan beside it. The opening separates audience, product direction and delivery sequence. Later slides connect the public recipe, onboarding, the dashboard and the place for integrations inside Developers.
The sequence matters: validate the pricing modal and the “Start Now” entry, build the dashboard and public recipes, then connect Beacon and persona campaigns. Each stage needs a destination that actually exists before the next one can send people there.
What the onboarding audit changes
The existing onboarding structure can stay brief, but its questions and destination need to support the job someone came to do. Preparing favorites or categories does not necessarily prepare a marketer to produce a client brief. My design proposal is to preserve the intent from the entry point and carry it into a relevant next action.
The first useful test is a complete journey: understand a public example, enter the product without losing its parameters, connect a supported tool and obtain a result that can be verified. A new API key alone does not demonstrate that outcome.
September 22: the dashboard becomes Recipes
The direction survived contact with the next conversation, but the name did not. In a working session with Jon Farjo on September 22 the feature was renamed Recipes, and the direction was approved to build. The decisions that matter from that session:
- The prompt is the primary interaction. The user writes what they want; the system maps it to a topic, metric, timeframe and component. A guided stepper stays available for manual adjustment, but asking is the front door.
- Recipes replace the API docs for most users. Each recipe bundles the relevant endpoints, the working code and the user's key around one use case. Only a small fraction of traffic ever reaches developer documentation; most people take a key and work inside their own tools.
- Persona-driven sets. Marketer, Investor, Developer and a new Enterprise persona filter what a user lands on, and the persona must be changeable in account settings.
- Free and logged-out users participate. The same rule as the API applies: recent data real, social data scrambled, with the page saying so plainly. That boundary is the upsell, not a wall.
- Recipe pages are public landing pages (one URL per recipe, the same page for every user state) and the raw material for distribution: persona-routed social posts, a weekly recipe email, a use-cases section on the homepage.
- No generative inference in the builder. The builder uses a decision model that assigns probabilities to predefined options. Free-form generation stays in the user's own LLM, outside the product.
Community sharing stayed deliberately simple and later. The expectation set in the session is about two weeks of focused work.
Testing whether a decision model can carry the prompt
The prompt-first decision depended on an empirical question: can a small decision model reliably pre-fill the guided steps from a written idea, without generating text? I tested it before designing it in.
The test treats the user's idea as state and asks the model typed questions (format, entity type, metric, time window, sentiment), each with an explicit "not stated" option and a confidence per answer. Against thirty hand-written ideas with expected labels, including ambiguous, partial, Spanish-language and self-correcting cases, the measured run answered the format, metric and window questions correctly on every idea, and the two misses on other questions landed below the 0.7 confidence gate, meaning the product would have left those steps open rather than pre-filling them wrong. Median latency was 187 ms and a call costs a fraction of a cent, so pre-filling every idea for a thousand active users costs a few dollars a month. That order of magnitude, documented on a cost-scenario board, is what made the decision safe.
I then extended the same approach from five questions to the whole public API surface: a resolver maps the model's typed answers onto the real endpoint catalog (thirty-seven endpoints) deterministically, with availability rules per entity family. On a forty-prompt test set that included Jon's own examples, the resolved endpoint was correct on roughly nine out of ten prompts, with the residual variation sitting near the model's own confidence boundary.
A working prototype against real data
To make the flow reviewable, I built it: a small worker that serves the three screens of the flow (write the idea, confirm what to track, the recipe itself) against live data. The recipe screen renders the component the plan names: a chart card in the product's own chart conventions, tables with user-controllable columns, post feeds, plain counts, and the eight category visualizations the product already uses. The right panel derives a Claude Code/Codex prompt, an embed snippet marked as proposed, and a cURL call from the actual resolved request.
Two design problems surfaced and got their own screens. First, ambiguity belongs to the resolver, not the model: "GE" may be a stock or a noisy two-letter token, so a confirmation screen shows each resolved subject as an existing entity with live figures as proof, with runners-up one click away. Second, exact phrase co-occurrence counts require creating a custom aggregation that only starts counting when it exists, so the waiting period became a designed collecting state, with progress, partial figures and a cross-sell into the product's collections, instead of a silent failure.
Verified against Jon's session examples: mention counts for co-occurring phrases, a top-20 stocks ranking by social dominance, and a multi-brand influencer table all resolve and render from the live API. The prototype runs on my personal infrastructure and is a design artifact, not shipped product.
Paper carries the UX, not the UI
One rule I settled this week after several rounds: what moves from the prototype into Paper is the experience (screens, states, copy, flow), never the prototype's own visual implementation. The current Paper page holds the prompt-first flow rebuilt with the file's own navigation components and the product's reference type scale, with Recipes distinguished by its own accent color in the rail. Earlier alternative rows (catalog search first, and a free-form LLM proposal) moved to an archive page marked as not current, preserved because they explain the decision.
September 23: the Developers section becomes buildable
The same direction reached the Developers section the next day. Integrations stopped being its own navigation item and moved inside Developers, under Other Ways In, while Recipes moved the opposite way: out of Developers, into its own top-level section, the Discover / Developers / Recipes navigation Jon approved. The old screen that still held Recipes inside Developers was deleted rather than archived twice.
Then the version got audited against what an implementation ticket actually needs, and the audit was blunt: the desktop composition was complete as visual direction but not as a spec. No mobile existed, states were missing, and several data points on the screens had no backend behind them. The response took two forms.
First, a phase split without duplicating screens. Everything that depends on backend work carries an amber Phase B label pinned to the specific element, nine labels in all; everything unlabeled is Phase A and can be built now. The split survived a correction that changed its meaning: the free policy is not data delayed by 24 hours, it is the same real last-24-hours window free users already see in the app, applied consistently to the API. One probe against the product's own admin also moved two cards from Phase B to Phase A, proving the usage-by-key data already exists on our side.
Second, the missing definitions became screens. A post-signup nudge and a no-key-yet Overview for the user who just arrived. A locked-endpoint state for a free user hitting a paid endpoint. Real dates on every usage figure instead of a relative last 30 days. Enterprise integrations with their real logos. Recipe outputs aligned with the API reference's own response views: JSON, table and schema tabs instead of two. And a states screen, B12, that defines the shared loading, empty, error and copied patterns for every Developers screen: a copy button that says Copied for a moment and returns at the same width, a run that keeps the last result visible while the new one arrives, and the three failure states (bad key, not on your plan, daily limit) each with its own next action.
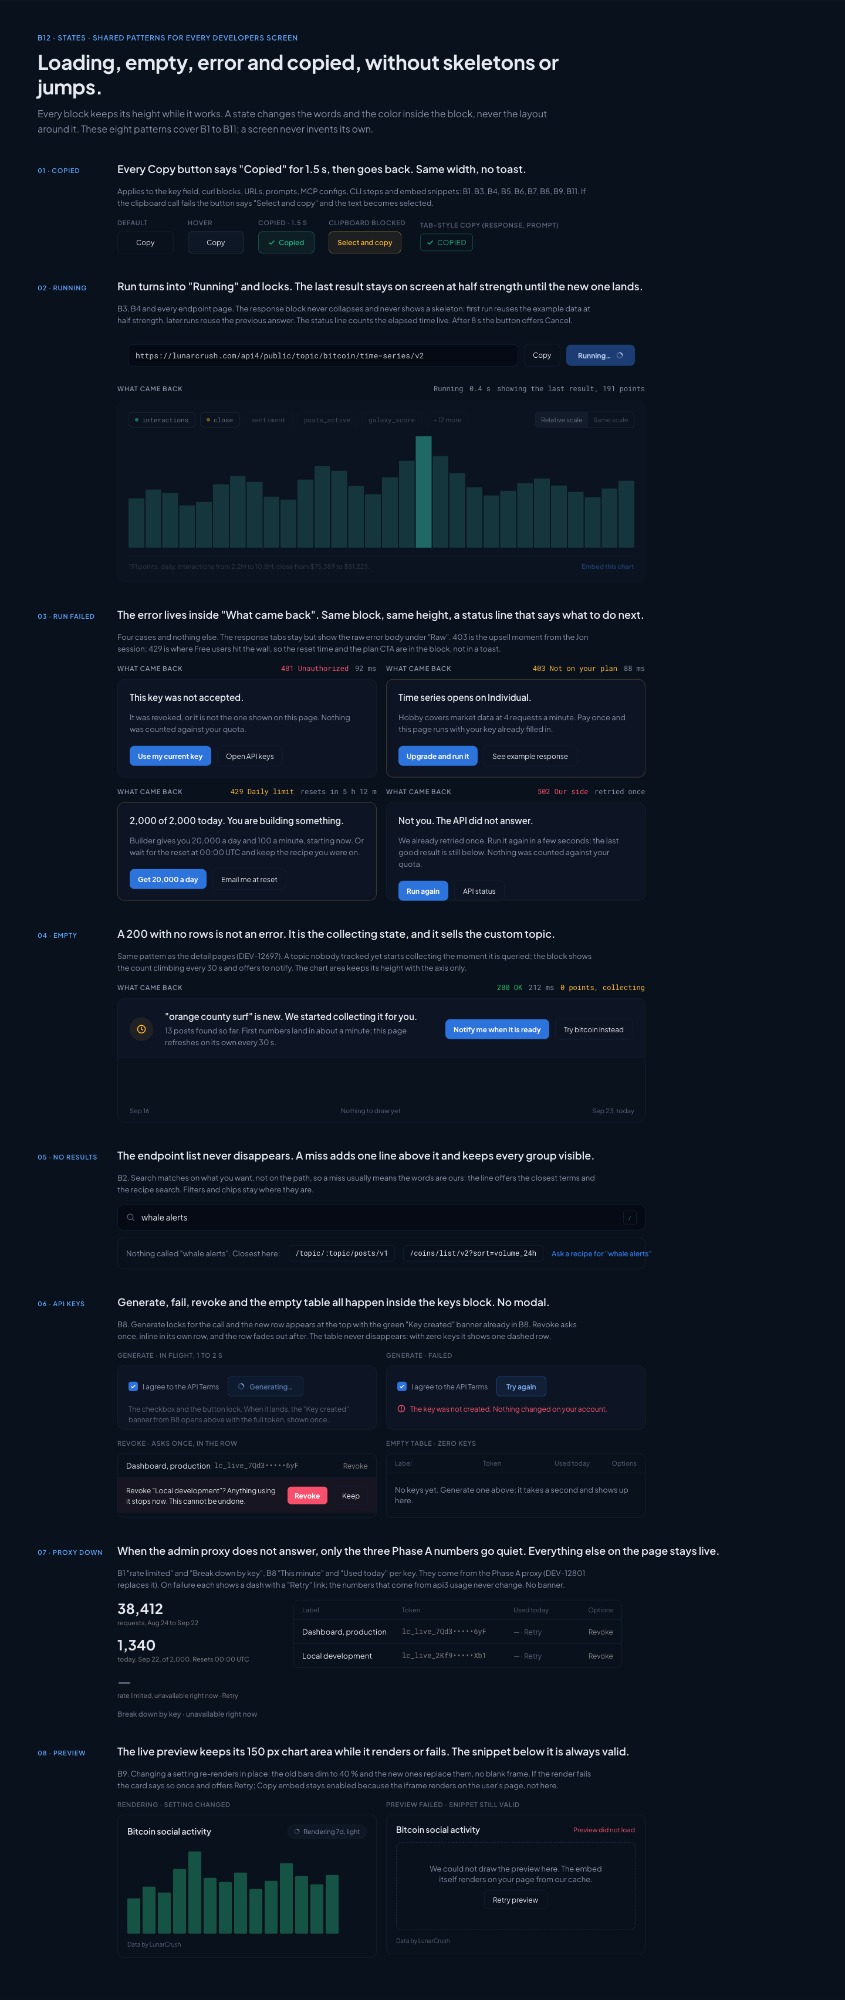
The states screen added at the end of the audit. Loading, empty, error and copied, without skeletons or jumps, defined once for all thirteen screens.
The band closed in build order: thirteen screens in numeric sequence, each with desktop, mobile and tablet rows, under a label that says plainly this is the one we build. The earlier explorations moved to a backup page so neither Joe nor the ticketing process trips over them.
October: the prototype grew into a product candidate
Work resumed on October 10 from a Slack message by Jon: non-developers cannot use LunarCrush data outside the Claude and ChatGPT connectors, and he asked for Zapier, IFTTT, Slack, Google Sheets and Notion. The recipe's output panel was rebuilt around Send to, with those tools first and the developer outputs behind a divider. The same week I measured whether the decision model was still the right engine: against the forty labeled prompts, it resolved 95 percent of endpoints at around 170 ms, while the two alternative models tested reached 83 and 78 percent at three to four times the latency. The original choice held.
Jon's next review bent the design harder: the flow was "overwhelming, logical but a lot". The response was subtraction. The model's name disappeared from every user-facing surface, the create screen went down to a title, one question box and three quiet suggestions, the confirm screen kept only the subjects, and the customize panel became a single change box with undo. The confirm screen then became a table of topics with live mentions, engagements and rank per row, so the proof that a subject exists is data, not copy. After an October 13 call, the open prompt gave way to a guided flow for first-time users: what do you want to make (a social post, an image, the numbers, a report, data in my sheet, data for my app), then subject, metric and look, with real series behind every preview. A backtest intent came out of a customer call the same day: a social metric against price over 90 to 365 days, plain arithmetic on the real daily series, labeled plainly as not a prediction.
Then the deliveries became real. A recipe sent anywhere becomes a live recipe on the worker, with public outputs the tools already read: a CSV that Google Sheets imports with one formula, an embed page Notion loads, RSS that Slack, Zapier and IFTTT poll, webhooks, and email through the product's own sending path. Slack got a real OAuth app. By October 28 every result type could be sent, including rankings and post lists with their creators and links, and the code had been reshaped to the webapp's own structure, with final paths, a migration table and the three open decisions (credits, account ownership, storage) written down for Jon.
Quality got its own pass instead of a promise: four persona agents (a crypto trader, a brand marketer, a financial researcher, a developer) ran two rounds of free-text and guided tests, their final screenshots went to a testing page in Paper, and the 77 prompts they produced became the regression set, later extended with 41 guided scenarios. Two full audits came out of it, fixing entity resolution (named lists in order, coin sectors, @handles, everyday aliases like Coke), visualization behavior (bubbles that always fit, readable treemaps, subscript zeros for tiny prices) and honest edge cases: a phrase co-occurrence count says it is a sample until a saved collection makes it exact.
Where the work stands
A direction approved to build, a measured basis for the prompt interaction, and a prototype that has outgrown the word: guided and free-text flows against live data, real deliveries into Sheets, Notion, Slack, Zapier and IFTTT, a 118-case regression set, and a documented migration path into lunarcrush.com. Still open: whether refreshes spend the user's credits, recipes owned by the account instead of a browser key, email sending secrets, and the Slack app's final approval in a workspace. The product build inside lunarcrush.com has not started; the handoff now includes the code shaped to fit it.
This continues the LunarCrush rebuild.